Weather Databricks Pipeline
Medallion ETL on Databricks SQL — Unity Catalog volume ingest, Delta bronze/silver/gold, quarantine table, DQ checks, workflow job, and Lakeview dashboard on the same 167k-row weather panel
- Role
- Data engineer / analyst
- Stack
- Databricks SQLDelta LakeUnity CatalogETLData qualityKaggle Global Weather Repository
Context
Companion to Weather Trend Forecasting on the same Global Weather Repository dataset. Where the Jupyter project focuses on Kyiv forecasting, anomalies, and statistical inference, this repo implements a lakehouse-style pipeline in Databricks: land CSV on a Unity Catalog volume, transform in SQL into Delta tables, quarantine bad rows, publish gold aggregates, and monitor with DQ checks plus a dashboard.
Pipeline
- Bronze —
read_filesfrom the volume intoweather_bronze.global_weather_rawwithingested_at/source_file. - Silver — parse timestamps, dedupe keys, route failures to
weather_silver.global_weather_quarantine, clean rows toweather_silver.global_weather. - Gold — country/city/Kyiv aggregates and
gold_data_profilerow counts. - DQ — append check results to
weather_dq.pipeline_checks(latest run queryable for the dashboard).
Operations
- Job:
weather_medallion_pipeline(manual or scheduled re-run). - Dashboard: Weather pipeline ops (Databricks workspace; screenshots in the GitHub repo).
What this demonstrates
ELT on a lakehouse: raw land first, transforms in the warehouse, auditable quarantine path, and explicit DQ gates suitable for analyst-facing tables—not a one-off notebook export.
Highlights
- Catalog `weather_pipeline`: bronze ingest from `/Volumes/.../GlobalWeatherRepository.csv` with lineage columns
- Silver dedupe on `(location_name, last_updated)` — 167,811 clean rows, 2 quarantined; reconciles to 167,813 bronze
- Six automated DQ checks in `weather_dq.pipeline_checks` (duplicate keys, nulls, row reconciliation, Kyiv gold coverage)
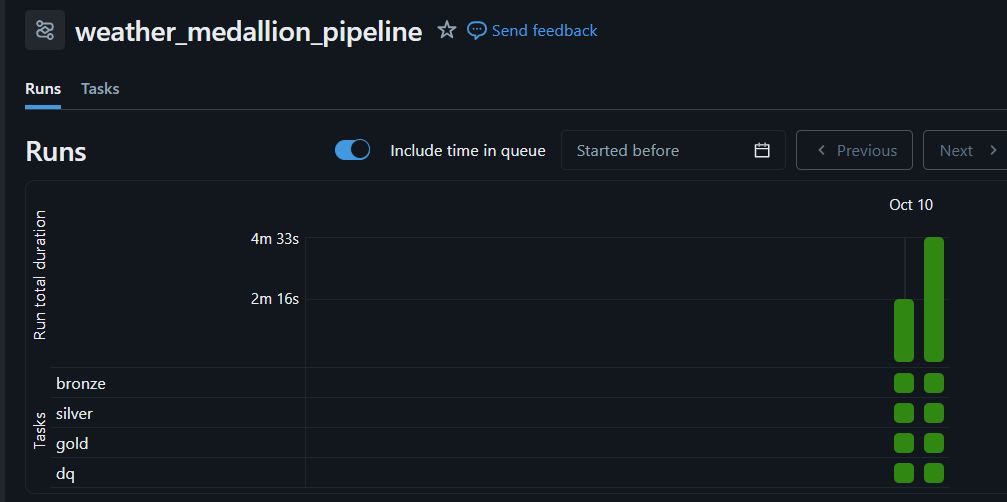
- Job `weather_medallion_pipeline`: four SQL tasks (bronze → silver → gold → dq) on serverless warehouse
- Lakeview dashboard: layer counts, latest DQ table, Kyiv daily temperature series
Challenges
Outcomes
- Public GitHub repo with idempotent SQL scripts and setup docs
- Successful multi-task job run (~4.5 min) and published dashboard with static screenshots in repo
- Pairs with Weather Trend Forecasting — exploration/forecasting in Python, pipeline and BI in Databricks